Local AI Inference vs Hosted API: General Questions for a Practical Decision
There is no universal choice between local inference and a hosted API. Use these questions and a short worksheet to clarify your data boundaries, workload, operating responsibilities and open requirements.
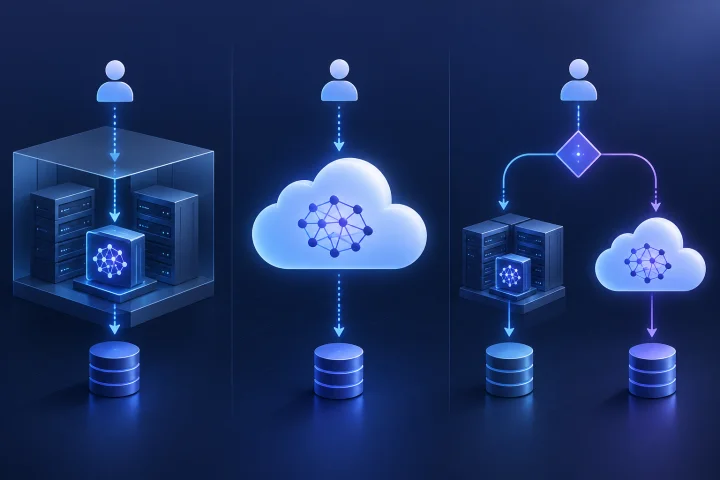
A set of questions, not a universal ranking
The paper [“A Cost-Benefit Analysis of On-Premise Large Language Models”](https://arxiv.org/html/2509.18101v1) describes a framework intended to help organizations assess when on-premise deployment may be economically viable. This article does not reproduce that framework or compare options using measured results. It offers general questions to help a team identify what it needs to investigate.
Application hosting and model inference are separate choices. A self-hosted application might be configured to use a model in the same environment, a hosted API, or more than one destination. The arrangement depends on the application and its configuration.
Avoid treating local inference as automatically more private, cheaper or faster, or a hosted API as automatically simpler or a better fit. Assess the particular setup against your requirements.
- Which component receives a user request first?
- Where is model inference configured to take place?
- Which requirements would rule out a destination?

Define the data and workload
Trace a representative request through the proposed arrangement. Note which components handle it and what information is involved, such as user input, attached or retrieved material, model output or operational records. Confirm relevant details using the documentation for the specific application and provider.
Describe the work the system is meant to do before comparing options. List representative tasks, input and output formats, expected patterns of use, and what your team would consider an acceptable result. These are prompts for defining a test, not universal evaluation criteria.
- What information would each component handle?
- Which data-handling, access or retention details need confirmation?
- Which tasks and usage patterns represent the intended workload?
- What output limitations or review requirements matter?

Identify responsibilities and dependencies
For local inference, identify the model, runtime and compute arrangement under consideration, then consult their official documentation for requirements and responsibilities. For a hosted API, check the particular provider’s current documentation and terms for details relevant to your use, such as data handling, access controls, quotas, limits and failure behavior.
For either approach, consider which components the application depends on, who would configure and maintain the arrangement, and what your team can support. Estimate costs using your own workload and operating assumptions rather than relying on a general claim that one approach is cheaper.
- Which documentation describes the model, runtime or provider?
- Who would configure and maintain the arrangement?
- Which dependencies or failure cases need consideration?
- What workload and operating assumptions belong in a cost estimate?
A short decision worksheet
Use this worksheet to turn open questions into a focused comparison. Fill it in for the specific configurations you are considering; leave an item marked unresolved when you do not yet have an answer.
bullets
- Required tasks and representative test material: __________
- Data boundaries and details to verify: __________
- Candidate inference destinations and their documentation: __________
- Responsibilities, dependencies and operating assumptions: __________
- Questions the comparison should answer: __________
- Reviewer, decision owner and unresolved issues: __________
Treat hybrid inference as a design choice
A hybrid arrangement may be considered when a team wants different inference destinations for different requests. Whether it is possible and how it behaves depends on the application and its configuration.
Before relying on one, specify the intended routing rules, permitted destinations and fallback behavior. Check the relevant documentation and configuration to determine whether those rules are supported as intended; do not assume a fallback is available or preserves a desired data boundary.
- Which requests, if any, are intended for each destination?
- What should happen if a destination cannot complete a request?
- Does the documented configuration support the intended routing?
Keep application hosting separate from inference hosting
Managed hosting for an AI application does not, by itself, establish where that application’s model inference runs. Airbip offers managed deployment for a public catalog of business, publishing, analytics, collaboration and AI applications. Application instances run as Docker workloads on Airbip cloud servers. Airbip automates routing and TLS certificates through Traefik and Let’s Encrypt, includes DNS checks and service lifecycle management, and provides configurable daily, weekly and monthly backups. Customers can use an Airbip subdomain or a compatible custom domain.
These hosting capabilities do not determine an application’s inference configuration or remove customer responsibility for data, access and governance choices. Check the specific application’s configuration and documentation to establish its model endpoint and requirements. Consult the live Airbip website for current plans and commercial terms.
Airbip may be relevant when the requirement is managed hosting for an application in its catalog. Assess a requirement for a particular inference environment or provider arrangement separately.
- Confirm application hosting and inference location as separate details.
- Determine who is responsible for data access, model configuration and governance.
- Consult live service information for the deployment and terms you are considering.
Frequently asked questions
Does self-hosting an AI application mean its inference is local?
No. Application hosting and inference location are separate details. The application’s configuration determines which model endpoint it uses.
Is local inference automatically more private, cheaper or faster?
No universal conclusion follows from location alone. Assess the particular configuration, workload and requirements.
What should I check before using a hosted model API?
Review the specific provider’s current documentation and terms for details relevant to your use, including data handling, access controls, quotas and failure behavior.
How can I compare local and hosted options?
Define the questions you need answered, use representative tasks and approved test material, record the configurations and observations, and note unresolved issues. A limited comparison applies to the configurations tested, not necessarily to other workloads.
What should I consider for hybrid inference?
Check whether the application supports the intended routing, identify the destinations for relevant requests and specify what should happen if a destination cannot complete a request.
Sources and further reading
- A Cost-Benefit Analysis of On-Premise Large Language Models — arXiv
- Docker documentation — Docker
- Traefik documentation — Traefik Labs
- Let’s Encrypt documentation — Internet Security Research Group
- OWASP Top 10 for LLM Applications — OWASP