Self-Hosted AI Does Not Automatically Mean Private: A Data-Flow Checklist
Hosting an AI application yourself does not prove that prompts, files, logs or backups stay on your infrastructure. Trace every data path and verify each destination before using sensitive information.
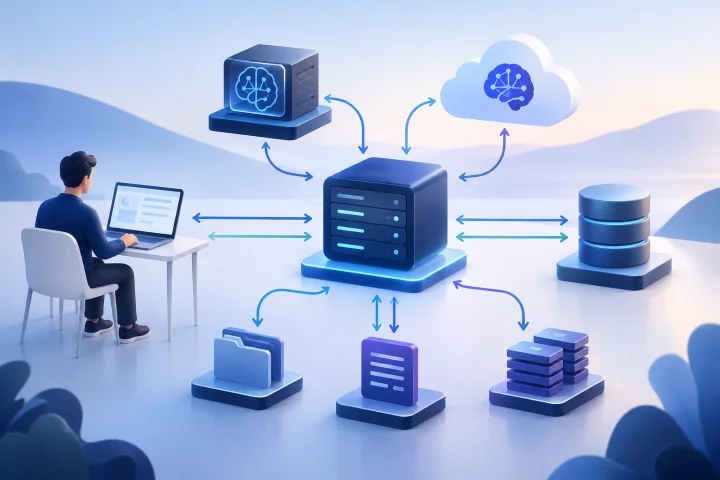
Self-hosted describes a deployment choice, not a complete privacy outcome
A self-hosted AI application runs on infrastructure you or a hosting provider arrange. That fact alone does not tell you where inference happens, which services receive data, what gets retained, or who can access operational copies.
Treat the application and the model endpoint as separate parts of the system. [Ollama’s API introduction](https://github.com/ollama/ollama/blob/main/docs/api/introduction.mdx) describes a local API address as well as a cloud API base URL. Its [authentication documentation](https://github.com/ollama/ollama/blob/main/docs/api/authentication.mdx) also explains that cloud-model requests can be made through its local API. A request sent to a local interface is not, by itself, proof that model processing is local.
The right question is not simply “Is this self-hosted?” Ask instead: “For this workflow and these data types, which systems process or store information, under what terms, and how can we verify that?”
- Application hosting: where the user-facing interface and its supporting services run.
- Model hosting: where inference occurs and which endpoint receives requests.
- Data handling: what is stored, logged, backed up, transmitted, or made available to operators and connected services.

Draw the complete data path before deployment
Map the real workflow from the person using the system to every component that might handle information. Include the AI application, model endpoint, database, file store, reverse proxy, connected tools, analytics or monitoring services, and backup destination. Add human access paths such as administration, support, and incident investigation where applicable.
Mark each connection as local to the deployment or external to it, and note who operates each destination. “Local” should mean local to the relevant machine or environment, not simply “reached through a local-looking interface.” Confirm the configured endpoint and the model or service it actually calls.
Do this for each feature you plan to use. Chat, document search, file upload, retrieval, and integrations can have different paths. Do not assume that a feature’s data handling follows the same rules as ordinary chat.
- Draw arrows for requests, responses, synchronization, logging, and backups.
- Label each destination with its operator, environment, and purpose.
- Record which connections are optional and whether disabling them changes the workflow.
- Check configuration and network behavior against current product documentation; do not rely on a product label or a default setting as proof.

Inventory the data, not just the documents
List the information that enters, is derived by, or is generated by the workflow. A document upload may lead to extracted text, chunks, embeddings, search results, prompts containing retrieved passages, and generated responses. Whether each item exists depends on the application and configuration, so verify it rather than assuming.
Include ordinary operational metadata. A service may record timestamps, account identifiers, request paths, error details, model selection, or usage information. Logs can contain more than teams expect if requests or errors include sensitive values.
For each data type, describe its sensitivity, purpose, destination, and whether the workflow needs it at all.
- Inputs: prompts, pasted text, uploaded files, images, and information retrieved from connected sources.
- Derived data: extracted text, chunks, embeddings, indexes, cached content, and summaries, if the system creates them.
- Outputs: generated responses, citations or retrieved passages, and files created by the application.
- Operational data: application logs, proxy access logs, analytics, error reports, usage metadata, and administrative records.
- Copies: database contents, file volumes, snapshots, exports, and backups.
Verify each destination’s processing and retention terms
For every service in the map, consult current primary documentation and the applicable agreement. Record what the service receives, where processing occurs, which regions or subprocessors may be involved, how long information is kept, who can access it, how deletion works, and whether data may be used for other purposes.
Do not treat one provider-wide statement as a complete answer for every feature. [OpenAI’s platform documentation](https://platform.openai.com/docs/models/default-usage-policies-by-endpoint), for example, distinguishes abuse-monitoring logs from application state and presents retention information and controls by endpoint. Review the exact endpoint and feature your application uses.
If personal data is subject to the GDPR, relevant items include data minimisation, storage limitation, security, recipients, and transfers. The [European Commission’s GDPR principles guidance](https://commission.europa.eu/law/law-topic/data-protection/information-business-and-organisations/principles-gdpr_en) covers these principles and transparency information. Where a provider processes personal data on behalf of a controller, check the applicable processor contract and its scope, including conditions for engaging another processor under [GDPR Article 28](https://eur-lex.europa.eu/eli/reg/2016/679/oj/). This is an operational checklist, not a substitute for legal advice.
- Processing: what data is sent, for which feature, and in which region or environment?
- Retention and deletion: what persists, for how long, and what happens to backups or derived data after deletion?
- Access and reuse: who can access the data, and is it used for training, service improvement, abuse monitoring, or another purpose?
- Contract and subprocessors: which terms apply to your account and use case, and how are other processors covered?
- Evidence: save the documentation version or agreement reviewed, the date, and any questions that remain unanswered.
Include logs, backups, and other operational copies
A prompt can be absent from the main chat database and still appear elsewhere. Check application logs, reverse-proxy access logs, analytics, error reports, support workflows, database exports, persistent file storage, and backups. Identify both automated copies and copies people can create during troubleshooting.
[Docker documents volumes as persistent data stores](https://docs.docker.com/engine/storage/volumes/) and provides procedures for backing them up and restoring them. Its [logging-driver documentation](https://docs.docker.com/engine/logging/configure/) describes drivers that can send container logs to local or external destinations. [Traefik’s access-log documentation](https://doc.traefik.io/traefik/observe/logs-and-access-logs/) describes configurable request fields and headers, including options to keep, drop, or redact fields. Inspect your actual configuration rather than assuming logs are harmless or local.
For backups, establish what is included, where the backup is kept, who can access it, how long it remains, and how deletion requests are handled. Confirm those details for the service and plan you actually use.
- Inspect logging configuration for request bodies, headers, query parameters, error details, and external log destinations.
- Check whether persistent volumes contain uploads, indexes, chat history, or other application state.
- Document backup scope, destination, access, schedule, retention, restore process, and deletion behavior.
- Review support and administrator access paths, including how access is granted and removed.
Test the real workflow with representative data
Documentation describes intended behavior; a controlled test helps establish what your deployed configuration actually does. Use synthetic or approved test content, not sensitive customer records, until the data path and terms are understood.
Submit a distinctive test phrase through each workflow and check the destinations you can inspect: application records, persistent storage, configured logs, proxy logs, connected services, and model endpoint settings. Where you cannot inspect a destination directly, request evidence or clarification from its operator. Test deletion too, and distinguish removal from the active application from expiration of backups or other retained copies.
[HTTPS protects traffic against certain in-transit risks](https://letsencrypt.org/docs/why-all-https/), but it does not establish what happens after a service receives the data. Treat transport security, processing location, retention, and access as separate checks.
- Run one test per feature: chat, file upload, document retrieval, integrations, and any export or sharing path.
- Verify the actual model endpoint and configuration; a local API address alone does not prove local inference.
- Search for the test phrase or test file in systems you administer, and note which destinations cannot be inspected.
- Test deletion and retrieval behavior, including whether the data remains in backups or external services.
- Repeat the check after material configuration changes or when a provider’s terms change.
Turn uncertainty into decisions and operating rules
Some questions will remain open because a provider’s public documentation may not cover your exact account, endpoint, or contract. Record those gaps instead of turning an assumption into a privacy claim. Assign an owner and a deadline, and identify what data can be used while the question is unresolved.
Define rules that fit the evidence: which information is allowed, which must be removed or masked, which workflows are prohibited, and who can approve exceptions. Make the rules usable by the people entering information, not only by the team that deployed the system.
For personal data, align the documented purpose, data minimisation, retention, security, recipients, and transfers with the obligations that apply to your organization. Keep a record of the systems and terms reviewed so that changes can be assessed later.
- Use a simple status for each flow: verified, conditionally allowed, blocked, or still under review.
- Assign owners for endpoint configuration, vendor terms, logs, backups, access, and user guidance.
- Set a clear rule for sensitive data while any material question remains unanswered.
- Review the map when adding a model provider, integration, new data source, logging destination, or backup path.
Choose the deployment model that meets verified requirements
Self-hosting the application can provide control over the application environment, but it does not guarantee that every model call or operational copy remains there. An externally operated model service may be appropriate if its endpoint-specific terms, processing, retention, and contract fit your obligations. Locally operated inference may suit requirements that call for local model processing, but verify the request route and the surrounding storage, logs, and access controls.
Compare models on evidence, not labels. If a requirement says that data must not leave a particular environment, establish which components are included in that boundary and test the configured workflow. If you cannot verify a required condition, do not route the affected data through the system until you have a suitable answer or an approved alternative.
Airbip offers managed deployment of applications from its public catalog, with application instances running as Docker workloads on Airbip cloud servers. It automates routing and TLS certificates through Traefik and Let’s Encrypt, and provides configurable daily, weekly, and monthly backups. These capabilities can help with application infrastructure and lifecycle tasks, but do not by themselves establish where an external model processes data, the retention terms of a connected service, or the treatment of every backup copy. Check current Airbip product information and applicable terms for details relevant to your deployment.
- Choose application hosting based on who should operate the infrastructure and which administration responsibilities you can support.
- Choose a model endpoint based on verified processing, retention, access, deletion, and contractual requirements.
- Choose local inference only after verifying the model route and accounting for local storage, logs, backups, and administrative access.
- If the required data boundary cannot be demonstrated, keep that data out of the workflow or choose a different deployment model.
Frequently asked questions
Does self-hosting an AI application mean prompts stay on my server?
Not necessarily. The application may send prompts to a separate model endpoint. Check the configured route and current documentation for the exact model and feature.
What should I check besides prompts and uploaded files?
Inventory derived data such as extracted text and embeddings if created, generated responses, logs, analytics, error reports, persistent storage, exports, and backups. The exact list depends on the application and configuration.
Does HTTPS prove that data is private?
No. HTTPS protects traffic against certain in-transit risks. It does not establish a service’s processing location, access practices, retention, deletion, or reuse terms.
What if a vendor’s documentation does not answer a key question?
Record the gap, ask the vendor for applicable documentation or contractual clarification, and avoid sending data that depends on that answer until it is resolved. Use a lower-risk test dataset in the meantime.
Sources and further reading
- Volumes: Back up, restore, or migrate data volumes — Docker
- Configure logging drivers — Docker
- Logs and Access Logs — Traefik Labs
- Data controls in the OpenAI platform — OpenAI
- Principles of personal data processing under the GDPR — European Commission
- Regulation (EU) 2016/679, Article 28 — EUR-Lex
- Ollama API introduction — Ollama
- Ollama API authentication — Ollama
- Why All Websites Should Use HTTPS — Internet Security Research Group (Let's Encrypt)